

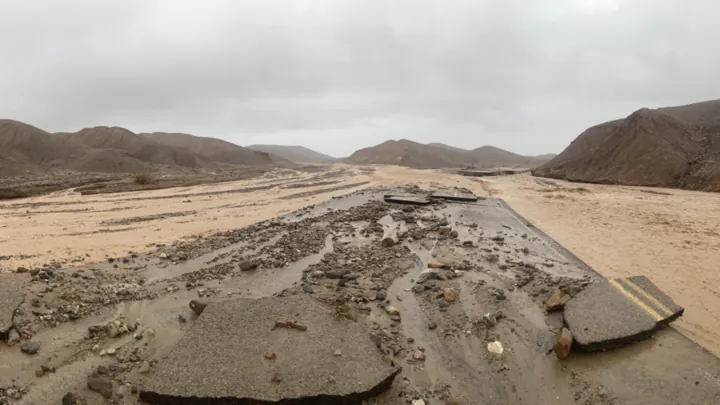
- Description
- Flood damage
- Source
- Unidentified National Park Service photographer · original page
- Licence
- PD Public domain
 Disaster cases: the SQL is clean, the assembly is wrong
Three workloads where no single query is bad, and yet they do not scale.
In brief
- A · Valuation: E1 E2 E3 E4 E5 E13.
- B · Hierarchy: E1 E4 E5 E13.
- C · Permissions: E1 E2 E5 E11.
- Common remedy: prepare what the loop was recomputing, then run very few queries.
Three realistic workloads where every query, taken in isolation, is clean: set-based inside, indexed, typed, reviewed. They all fail the same way: an assembly error, often several at once. For each one: the complete procedural version, the reason for the disaster (with references to the design errors), the measurements, and the redesign using the set-based approach: one preparation step, then very few queries, with no iteration.
Measurements were taken on SQL Server 2019 (LocalDB), on a development workstation, clearing the plan cache before each run (DBCC FREEPROCCACHE, test instance only). The statements, function calls and logical reads columns are exactly reproducible; duration and CPU vary from one run to the next (up to a factor of 2 on this machine): they are orders of magnitude, and it is the growth that matters. In each case, the equivalence of the results was verified (EXCEPT in both directions: no rows).
The three cases#
| Case | Scenario | Accumulated errors | Loop | Set-based |
|---|---|---|---|---|
| A · Valuation | One procedure per customer, one function per row, an audit trigger | E1 E2 E3 E4 E5 E13 | 188,002 statements, 180,000 calls (2,000 customers) | 4 statements, 0 calls |
| B · Hierarchy | One recursive CTE per node | E1 E4 E5 E13 | 40,002 statements (20,000 nodes); quadratic without an index | 2 statements, then 1 per recalculation |
| C · Permissions | One access function per user and per fact | E1 E2 E5 E11 | 200,000 calls, 59M reads (40 users) | 3 statements, 0 calls, 14,000 reads |
What the three have in common#
- Code review finds nothing. Each building block, looked at on its own, follows best practices.
- The unit test passes. One customer, one node, one user: a few milliseconds.
- The loop is somewhere other than in the query: in the orchestrator, in the function called per row, in the recursion launched per node.
- The cost is proportional to the number of iterations, and sometimes to their square, because each round rereads a structure that grows with the number of rounds.
- The fix is not an optimization. You do not make the loop faster: you remove it, by preparing what the loop was recomputing.
How the measurements were taken#
Four indicators, read after clearing the plan cache: the statements executed (sum of execution_count in sys.dm_exec_query_stats), the function calls (sys.dm_exec_function_stats), the logical reads and the CPU. The first three are reproducible; CPU and duration are only reproducible as orders of magnitude.
-- Measurement template (TEST instance only: DBCC FREEPROCCACHE clears the plan cache of the whole instance)
DBCC FREEPROCCACHE;
GO
DECLARE @t0 datetime2(7) = SYSDATETIME();

-- ... the workload to measure, in this same batch ...

SELECT DATEDIFF(MILLISECOND, @t0, SYSDATETIME())                                   AS duree_ms,
       (SELECT SUM(execution_count)          FROM sys.dm_exec_query_stats)          AS instructions,
       (SELECT ISNULL(SUM(execution_count),0) FROM sys.dm_exec_function_stats)      AS appels_fonctions,
       (SELECT SUM(total_logical_reads)      FROM sys.dm_exec_query_stats)          AS lectures_logiques,
(SELECT SUM(total_worker_time) / 1000 FROM sys.dm_exec_query_stats) AS cpu_ms;DBCC FREEPROCCACHE clears the plan cache of the whole instance: only run it on a test instance that you control.
