

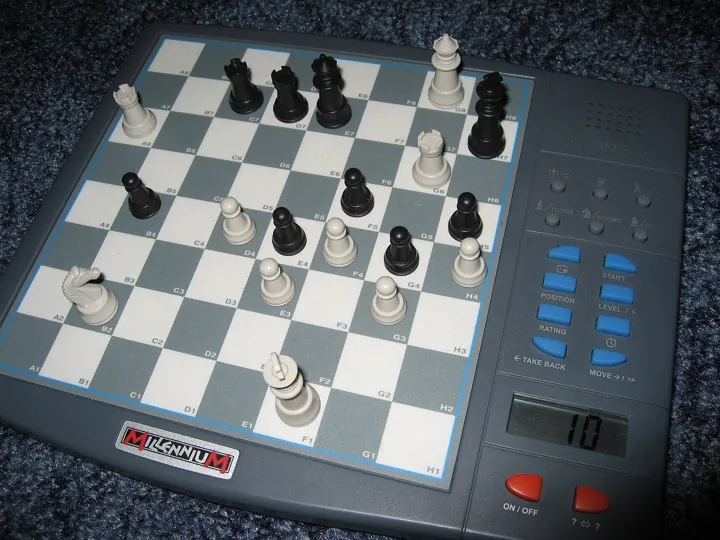
- Description
- Un petit ordinateur d'échecs électronique en pleine partie, pièces blanches et noires sur l'échiquier.
- Source
- Dezidor · original page
- Licence
- PD Public domain
 Hofstadter’s Law
Even when we know delays are natural and we build in buffer, we still end up late.
In brief
- What : a complex task always takes longer than expected, even if this rule has been taken into account.
- Why : self-reference: the correction we apply is itself estimated with the same optimism as the original estimate.
- Detect : “we already added buffer,” and yet the delay still happens.
- Avoid : adjust using your data, not your impression; break work down, deliver early, and revise estimates along the way.
Definition#
 Fictitious illustration
Hofstadter’s law is stated as follows: “It always takes longer than expected, even when taking Hofstadter’s law into account.” It is due to Douglas Hofstadter, who formulated it in Gödel, Escher, Bach: an Eternal Golden Braid (1979), regarding predictions of when a computer would defeat the best human chess players.
It is an empirical, intentionally paradoxical adage, not a cognitive bias in the strict sense nor a proven scientific law. Its strength is its self-reference: it is true because it applies to itself. It reminds us that we cannot solve the problem by adding an “intuitive” buffer, since the intuition setting that buffer is the same one that got it wrong in the first place. It is close to The Planning Fallacy, whose persistent effect it describes, and to Unrealistic optimism, of which it describes one of the drivers.
The mechanism#
No experiment has “proven” the law; however, we can explain why it is often observed:
- Recursion of optimism : we adjust our estimate (“let’s add 20%”), but the adjustment is itself decided with the same optimism that produced the estimate. The correction remains too small.
- Unexpected issues cannot be imagined in advance : we add buffer for known risks, not for those we cannot yet see.
- The distribution tail is heavy : a task’s actual duration is not symmetric around the average; a few very large overruns pull the average upward, and a buffer set for a “reasonable overrun” does not cover them.
- Effect of the buffer itself : a known buffer may get consumed (Parkinson’s law: work expands to fill the available time), so it is gone by the end.
- Misleading proportion : we estimate the visible part of a task; the final share of work (integration, testing, finishing) takes far more time than the beginning suggests. This is the “90-90 rule” attributed to Tom Cargill of Bell Labs: the first 90 percent of the code takes 90% of the time, and the last 10 percent takes the remaining 90%.
Where you encounter it#
In project management#
- Estimating : “I already added buffer”; the buffer itself is underestimated compared with historical data.
- Release planning : the date is pushed back three times, each time by “two weeks,” never by what observed velocity indicates.
- The last 10 percent : the project has been “almost done” for weeks; the ending (acceptance testing, fixes, production rollout) is what takes the most time.
- Story-point estimation : velocity is calibrated on past sprints, but commitments are made using the best observed velocity, not the median.
- External dependencies : we add buffer for our own work, not for waiting on a client decision or a third-party delivery.
In management#
- Commitments to leadership : a date is given “with buffer,” it still has to be postponed, and trust erodes.
- Transformation plans : the adoption time for a tool or method is revised upward at each milestone.
- Delegation : you ask a team member “how much time they need,” add what you consider reasonable buffer, and are surprised by delay.
- Hiring : the timeline “to find and onboard someone” gets longer whenever the time to true autonomy is not accounted for.
Famous cases#
“In ten years, a computer will be world chess champion” 1957-1997#
Biases at play: Hofstadter’s law, persistent optimism in a technology forecast.
What happened. In November 1957, at an operations research conference, economist and computer scientist Herbert Simon, Nobel Prize in Economics winner in 1978, together with Allen Newell, put forward four predictions “to be achieved within ten years,” including this one: a computer will be world chess champion, unless the rules forbid it from competing. The text was published in 1958 in the journal Operations Research. Over the following decades, programs improved, and each time people announced the goal was close. It was not until May 1997 that an IBM computer, Deep Blue, defeated the reigning world champion, Garry Kasparov, 3.5 points to 2.5, after six games. Hofstadter, writing in 1979, specifically had these repeatedly postponed forecasts in mind when stating his law.
What this illustrates
The authors were eminent, well-informed researchers who understood the difficulties. Even so, they underestimated duration by a factor of four, because of what they did not yet know: the complexity of the finish (playing at champion level) far exceeded that of the beginning (playing correctly). For your projects: the final quality, integration, or performance step is the one whose cost is hardest to predict. Never estimate it as a simple pro-rata of the rest.
The 90-90 rule and Brooks’s law 1975-1985#
Biases at play: Hofstadter’s law (similar formulations drawn from software practice).
In The Mythical Man-Month (1975), Frederick Brooks, who led development of the System/360 operating system at IBM, observed that “all programmers are optimistic” and that adding people to a late project makes it later (“Brooks’s law”). Ten years later, Jon Bentley reported in Communications of the ACM (1985) the “90-90 rule,” which he attributed to Tom Cargill of Bell Labs: “The first 90 percent of the code accounts for the first 90 percent of development time; the remaining 10 percent accounts for the other 90 percent.”
What this illustrates
These two adages are practical professional wisdom, not laboratory results. They point in the same direction as Hofstadter’s law: the end of a project takes longer than the beginning, and brute-force correction works poorly. When you are late, adding people or buffer “by feel” does not solve the problem; reducing scope or delivering in stages does.
Detection signals#
- “We already added buffer.” And we still overrun.
- The date has been pushed back several times, each time by the same duration (“two more weeks”).
- Progress has been “90%” for several weeks.
- The buffer is backed by no data: “let’s take 20%,” “let’s double it.”
- No one knows what overrun percentage the team had on its last three projects.
- A task’s buffer is consumed right away (work expands), and delay accumulates at the end.
Avoidance reflexes#
- Adjust with data, not a rule of thumb. Calculate the actual/estimated ratio from your latest projects (median and 80th percentile) and apply it, instead of adding “a little buffer.”
- Revise estimates as you go. After each milestone, recalculate the finish based on observed velocity, not hoped-for velocity.
- Deliver early and in small chunks. A short batch is easier to estimate; delay becomes visible from the first batch rather than at the end.
- Estimate the ending separately. Reserve an explicit line item for integration, acceptance testing, bug fixing, and production rollout.
- Announce a range and a confidence level. “Between 10 and 16 weeks, 80% confidence” is better than a single date with invisible buffer applied.
- Reduce scope rather than quality. When delay appears, cut features, not acceptance testing or tests.
- Place buffer at the project level, not the task level. A global reserve managed by the lead is less likely to be consumed than hidden buffer in each task.
With AI: detect, fix, mitigate#
AI can calculate real/estimated ratios from historical data without fatigue and recalculate an end date based on observed velocity. It cannot guess the unexpected events of a specific project, and its own duration estimates suffer from the same biases as its training data. Its main value is to instrument a correction method, not to replace judgment.
Detect#
- Measure the past gap between estimate and actual based on an export of tickets or milestones.
- Spot repeated postponements of the same date in a scheduling history.
- Identify implicit margins in an estimate (applied overrun rate, hidden buffers).
Fix#
- Recalculate a probabilistic end date based on actual velocity from recent sprints.
- Suggest a range based on your history, with the associated confidence level.
- List end-of-project tasks that are often forgotten for a given deliverable type.
Mitigate#
- Produce automatic tracking of drift, reviewed at each milestone.
- Alert when the date has been pushed back twice without a method change.
- Compare multi-person estimates, using their spread rather than their average.
Prompts to integrate into your workflow#
1. Correct the estimate with historical data. Use with an export of your estimates and actual durations.
Here is the history of our past work packages (initial estimate, actual duration, package type): [table].
1. Calculate, for each package type, the actual duration / estimated duration ratio: minimum, median, 80<sup>th</sup> percentile, maximum.
2. Say which conclusions are reliable and which are based on too few packages.
3. For a new package estimated at [value], give the duration to announce for “a one-in-two chance” and for “four chances out of five.”
Do not invent any data: if the history is insufficient, say so.
2. Revise the date during the project. At each milestone, with the actually observed figures.
Situation: [remaining work in units], observed velocity over the last [N] sprints: [values], current delivery date: [date].
Calculate a likely end date with a range (optimistic, likely, pessimistic) based on <em>observed velocity</em>, not expected velocity.
Specify what would make this projection too optimistic (project closeout, external dependencies, fixes) and suggest three scope-reduction decisions to meet the date if it is mandatory.
How to integrate them#
- During estimation: prompt 1 is used to correct an estimate with historical data before announcing it.
- At each milestone: prompt 2 replaces “we'll catch up” with a quantified projection.
- In retrospectives: keep the results to enrich the history: it's that history, not AI, that corrects the bias.
Precautions#
- A history that is too short or biased (only completed projects) gives misleading corrections: include abandoned projects.
- AI can produce incorrect calculations confidently: verify ratios on a sample.
- Do not present an AI calculation to a client as a commitment: it's a decision aid.
- Do not send histories containing confidential data to an unauthorized tool.
Limitations#
- Hofstadter's law is not a cognitive bias in the strict sense: it's an empirical law, formulated with humor, that summarizes a common experience. It was not established through controlled experiments and has no quantified formulation.
- It is unfalsifiable by design: for any estimate, whatever it is, one can say the law was already included. It is useful as a warning, not as a testable prediction.
- It does not apply to every task: for repetitive, well-measured, low-uncertainty activity, estimates are often accurate. It targets complex and new tasks.
- Not all projects run over: some finish early or on time; overruns, being more pronounced, are what pull the average.
- The “90-90 rule” and “Brooks's law” are professional wisdom, useful but not proven in a lab.
Sources and verification#
- Hofstadter (1979), Gödel, Escher, Bach: An Eternal Golden Braid, Basic Books — statement of the law; Pulitzer Prize 1980 (General Nonfiction category).
- Simon & Newell (1958), “Heuristic Problem Solving: The Next Advance in Operations Research,” Operations Research — the four predictions from 1957.
- IBM, “Deep Blue” — May 1997 match against Kasparov.
- Brooks (1975), The Mythical Man-Month, Addison-Wesley — programmer optimism, Brooks's law.
- Bentley (1985), “Programming Pearls: Bumper-Sticker Computer Science,” Communications of the ACM — the 90-90 rule, attributed to Tom Cargill.
- Buehler, Griffin & Ross (1994), “Exploring the planning fallacy,” Journal of Personality and Social Psychology — the experimental basis of the phenomenon.
- Parkinson (1955), “Parkinson's Law,” The Economist, November 19, 1955.
